
Time Series Regression: Trends, Seasonality & Stationarity

Table of Contents
When a portfolio manager forecasts next quarter’s bond returns, an economist evaluates whether a rate hike will slow inflation, or a risk analyst models volatility across market regimes, they all rely on time series regression — the branch of econometrics designed for data observed sequentially over time. Unlike cross-sectional analysis, where observations are independent, time series data is inherently dependent: today’s interest rate is closely related to yesterday’s, and last quarter’s GDP growth shapes this quarter’s outlook. This creates unique challenges — trends, seasonality, and non-stationarity — that require adapted assumptions and careful modeling. This guide covers what makes time series data special, the key model types, how to handle trends and seasonal patterns, and the OLS assumptions that underpin valid inference.
What Makes Time Series Data Special?
In cross-sectional regression, you observe many different units (firms, individuals, countries) at a single point in time, and the order of observations does not matter. In time series regression, you observe one unit — or a small number of units — over many time periods, and temporal ordering is fundamental. Rearranging the rows of a cross-sectional dataset changes nothing; rearranging the rows of a time series destroys the data’s meaning.
A stochastic process is a sequence of random variables indexed by time: {yt : t = 1, 2, 3, …}. We observe one realization — one possible path — of this process. The goal of time series regression is to estimate relationships between variables using this single realization, recognizing that history could have unfolded differently.
Several features distinguish time series data from cross-sectional data:
- Non-independence: Interest rates, inflation, and GDP growth all exhibit temporal dependence — past values carry information about future values. Even equity returns, often modeled as nearly uncorrelated, display weak but measurable serial dependence at short horizons.
- No random sampling: Cross-sectional regression assumes observations are randomly drawn from a population. Time series data is a single historical path, not a random sample. Stationarity and weak dependence replace the random sampling assumption.
- Multiple frequencies: Financial time series operate at different frequencies — daily (stock prices), monthly (CPI, housing starts), quarterly (GDP, earnings), and annual (fiscal data). The choice of frequency affects model specification and the number of available observations.
- Trends and cycles: Many economic series exhibit long-run trends (nominal GDP grows over time) and cyclical patterns (retail sales peak in Q4). These features must be addressed before estimation, or inference can be severely misleading.
Common financial time series include equity index returns, Treasury yields, inflation rates, exchange rates, corporate earnings, and macroeconomic aggregates like GDP and industrial production. Each of these series exhibits some degree of temporal dependence, and understanding business cycle dynamics often requires time series methods.
Static Models and Finite Distributed Lag Models
Time series regression models fall into two broad categories depending on whether the effect of an explanatory variable on the outcome is immediate or unfolds over time.
A static model assumes the relationship between y and z is contemporaneous — only the current value of z affects y:
Static models are appropriate when the effect of z on y is immediate and complete within one period. For example, a static Phillips curve regresses current inflation on current unemployment, assuming the tradeoff is contemporaneous.
A finite distributed lag (FDL) model allows z to affect y over multiple periods. An FDL of order q includes the current value plus q lags:
The impact propensity (δ0) measures the immediate change in y from a one-unit increase in z. The long-run propensity (LRP) measures the total cumulative effect after all lags have played out:
For example, consider how a change in the federal funds rate affects corporate bond yields. The impact propensity captures the immediate pass-through in the first quarter, while the LRP captures the total effect after the rate change has fully transmitted through credit markets — typically over 3 to 4 quarters.
For a hypothetical FDL example, suppose the policy rate rises by 1 percentage point at quarter 0 and stays there; quarter −1 is the period before the change. Hold all other influences on corporate bond yields fixed and compare with a no-change baseline. Let the current-quarter and next three lag coefficients be 0.30, 0.25, 0.20, and 0.10 percentage points of bond yield per percentage point of policy rate. The policy-rate increase remains in place as each lag enters; pp means percentage points, and LRP means long-run propensity.
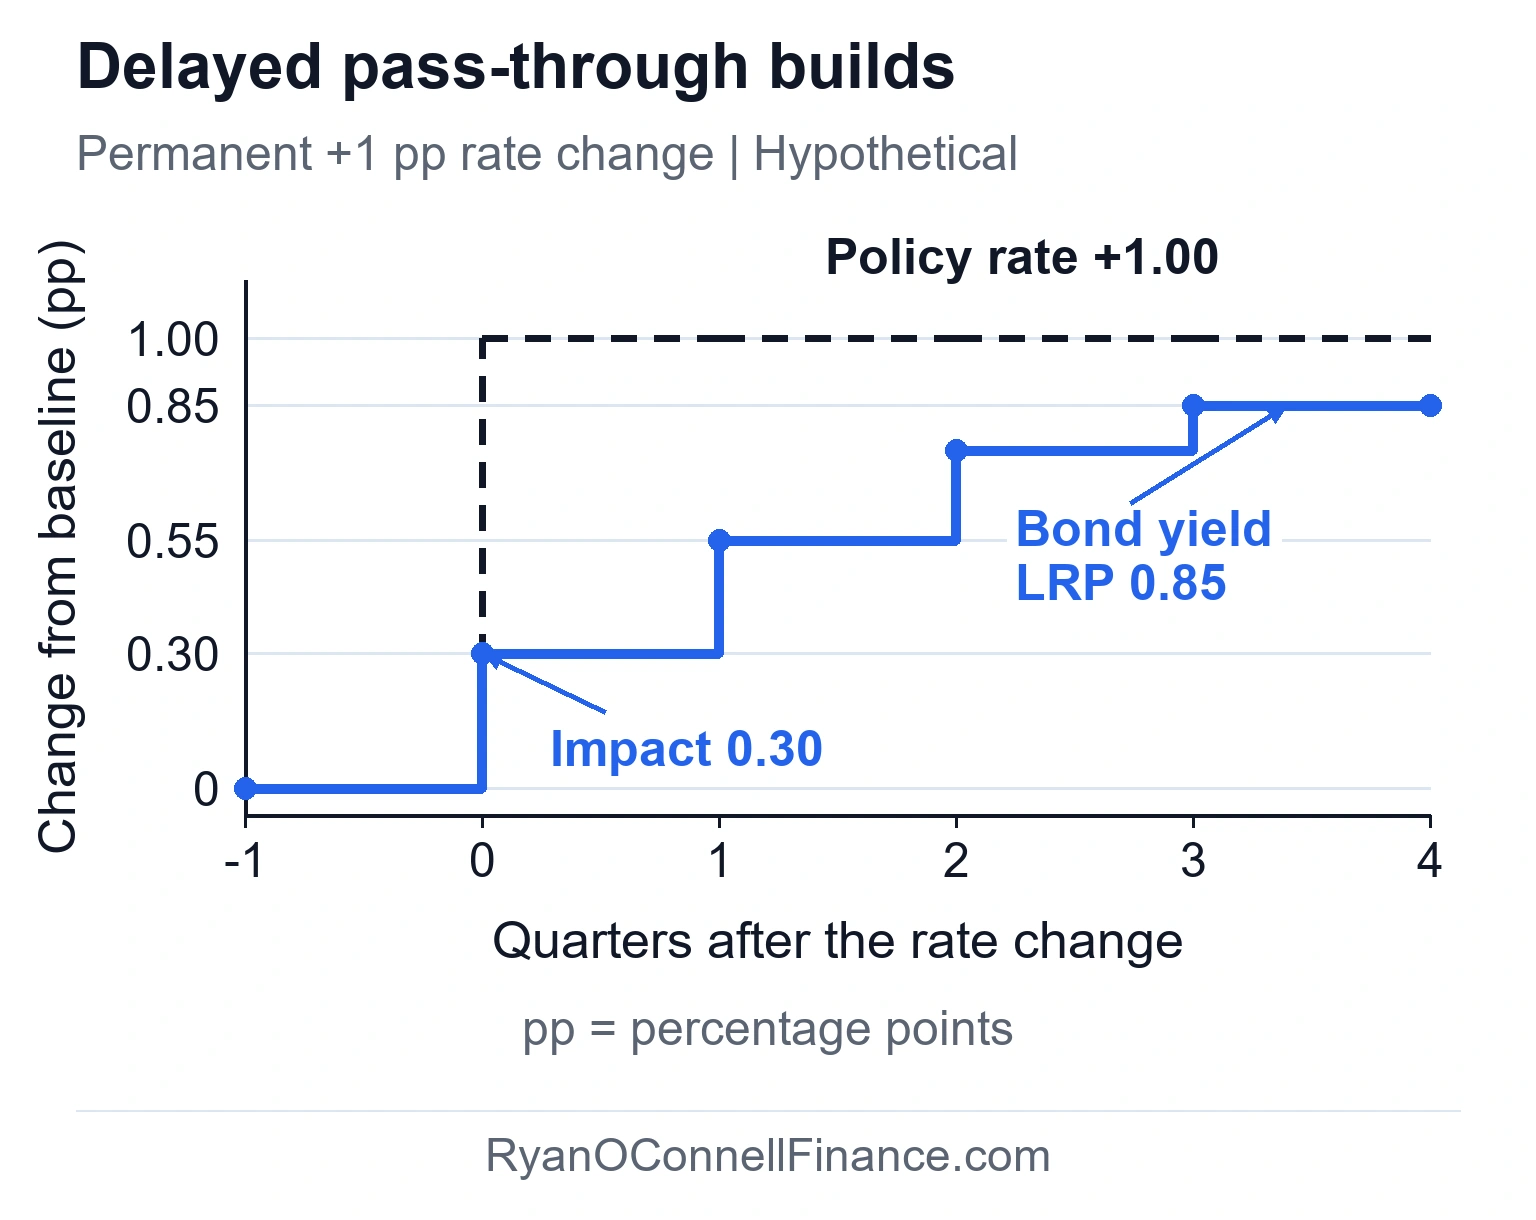
The bond yield initially rises by 0.30 percentage points, then reaches 0.85 percentage points by quarter 3 as all four coefficients contribute. The LRP is the eventual level difference under the permanent increase; it is not the sum of the plotted yield levels across quarters.
Multicollinearity among the lagged z values (zt, zt−1, zt−2, …) can make individual δ coefficients imprecise. However, the long-run propensity — their sum — can often be estimated precisely even when the individual lag coefficients are not statistically significant on their own.
Trends in Time Series
Many financial and economic time series exhibit long-run movements that must be addressed before regression analysis can produce valid results. These movements take two fundamentally different forms.
Deterministic Trends
A deterministic trend follows a predictable path over time. The most common specifications are:
Nominal U.S. GDP, for instance, is well-characterized by an exponential trend — it grows at a roughly constant percentage rate over time. A quadratic trend (adding a t2 term) can capture turning points, though it risks overfitting with limited data.
Stochastic Trends
A stochastic trend has no fixed path. The most important example is the random walk:
In a random walk, shocks are permanent — there is no tendency for the series to revert to a long-run mean. The 3-month Treasury bill rate is often modeled as a random walk because rate changes from Federal Reserve policy actions tend to persist rather than revert to a fixed level. Stock price levels also exhibit behavior consistent with random walks, which is why financial econometrics almost always models returns (which are approximately stationary) rather than price levels.
To isolate shock persistence, compare two hypothetical series starting at 100 in period 0. One follows a deterministic trend of 100 + 2t plus a stationary deviation that retains half of its previous value each period. The other is a random walk without drift. Give both a single +6-unit shock in period 2, with zero deviations beforehand and no further shocks. Compare each series with its own no-shock path: the rising deterministic trend for the first series and a constant 100 for the random walk. The shock effect below is the difference from that baseline, rather than the series’ total level.
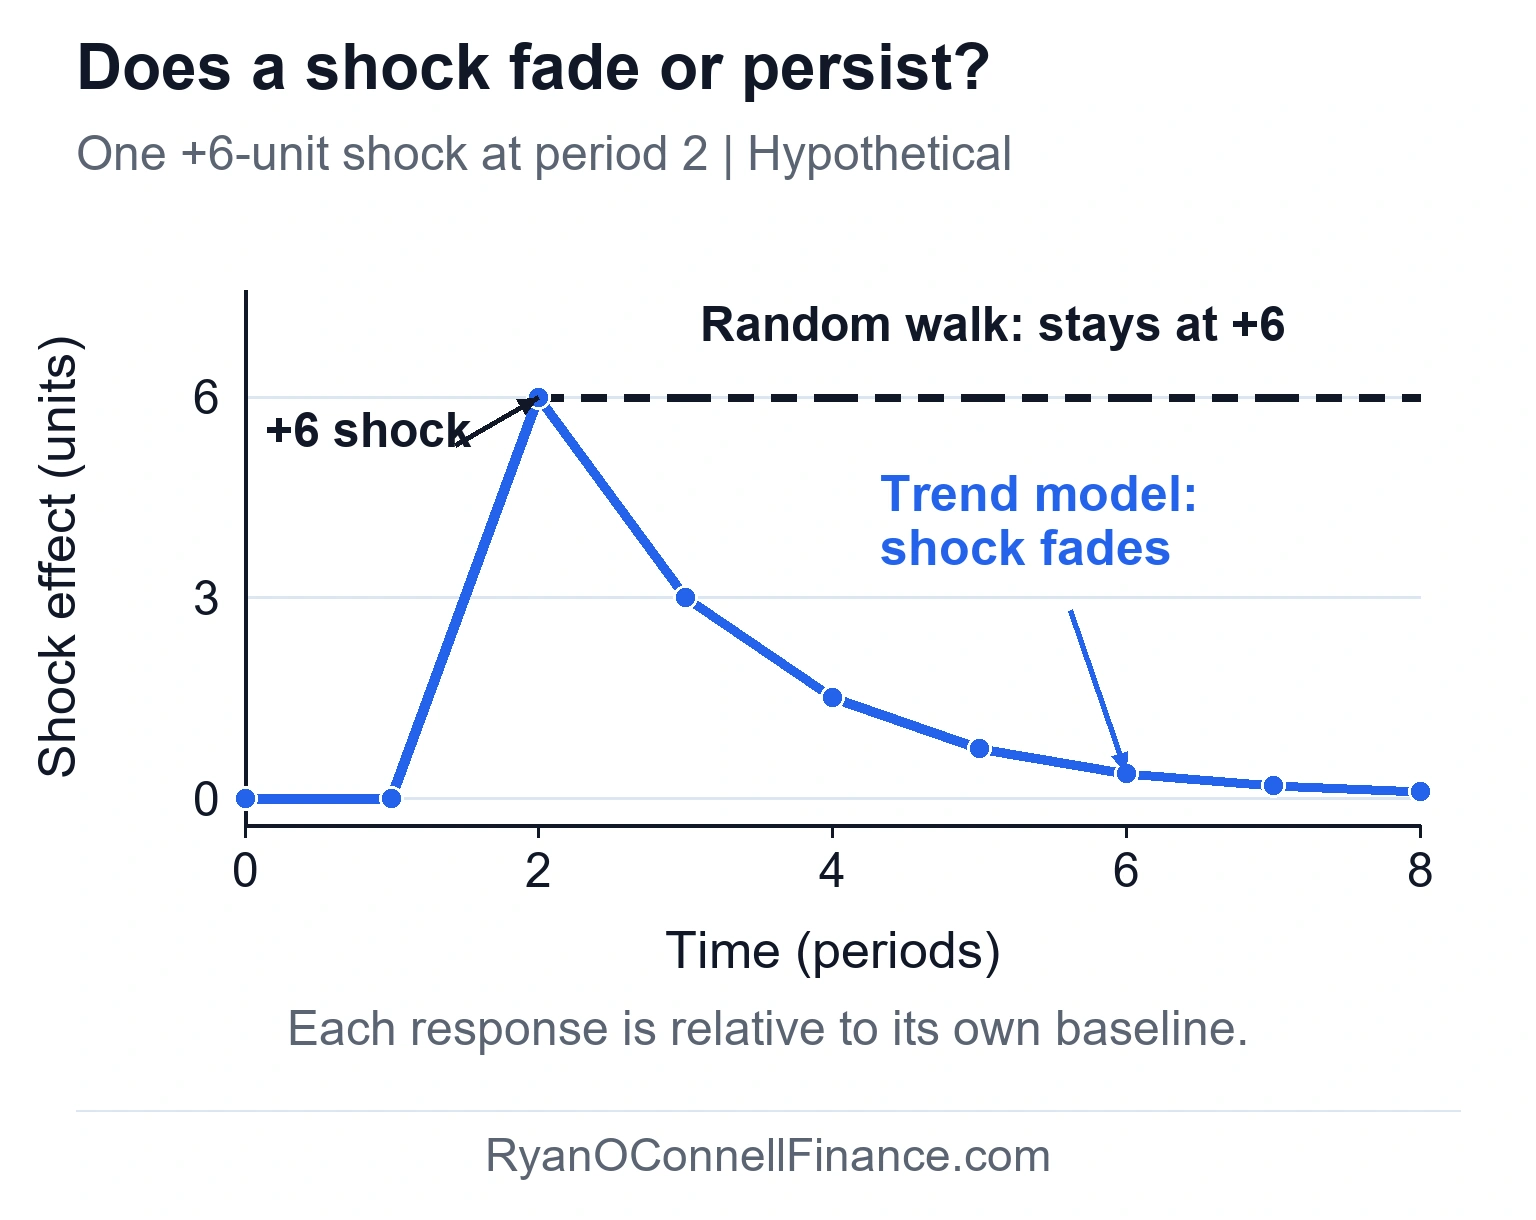
By period 4, the trend model is only 1.5 units above its baseline, while the random walk remains 6 units above its baseline. A deterministic trend supplies a predictable path to return toward; a random walk carries the shock into every subsequent level. These conditional responses illustrate persistence, rather than proving stationarity from a short observed path.
Regressing one trending variable on another — without controlling for the trend — can produce a misleadingly high R² and statistically significant t-statistics even when the variables have no true relationship. This is called spurious regression. For example, regressing housing investment on housing prices without a time trend may suggest a strong relationship that is merely an artifact of both series trending upward over the same period. Always check for common trends and include a time trend variable or detrend your data before estimation.
Including a time trend (t) as an explanatory variable in a regression is equivalent to detrending all variables first and then running the regression on the detrended values. After controlling for the trend, the regression examines whether movements above or below trend in x relate to movements above or below trend in y — a much more meaningful question.
For series with stochastic trends (random walks), detrending by including a time variable is insufficient. These series require differencing (taking yt − yt−1) or more advanced methods. For formal testing of whether a series has a unit root, see our guide on Cointegration and Unit Roots.
Seasonality and Seasonal Adjustment
Monthly and quarterly data often display recurring seasonal patterns. Retail sales surge in Q4 (holiday shopping), housing starts peak in summer months, and corporate earnings follow predictable quarterly cycles. If seasonality is present and unaccounted for, it can bias coefficient estimates and produce misleading significance tests.
The standard approach uses seasonal dummy variables. For monthly data, include 11 dummy variables (one for each month except the base month); for quarterly data, include 3 dummies:
Each seasonal dummy coefficient measures how much the dependent variable differs, on average, in that month compared to the base month (January). An F-test on the joint significance of all seasonal dummies tests whether seasonality is present in the data.
Consider a separate hypothetical retailer over two years, labeled Y1 and Y2. Underlying sales stay at $100 million every quarter, with no growth or random noise, but holiday shopping adds $30 million in each fourth quarter (Q4). Using Q1 as the base quarter, the known seasonal dummy coefficients are zero for Q2 and Q3 and +$30 million for Q4. Here, Q1-base adjusted sales means raw sales minus that known seasonal component; all other influences stay fixed.
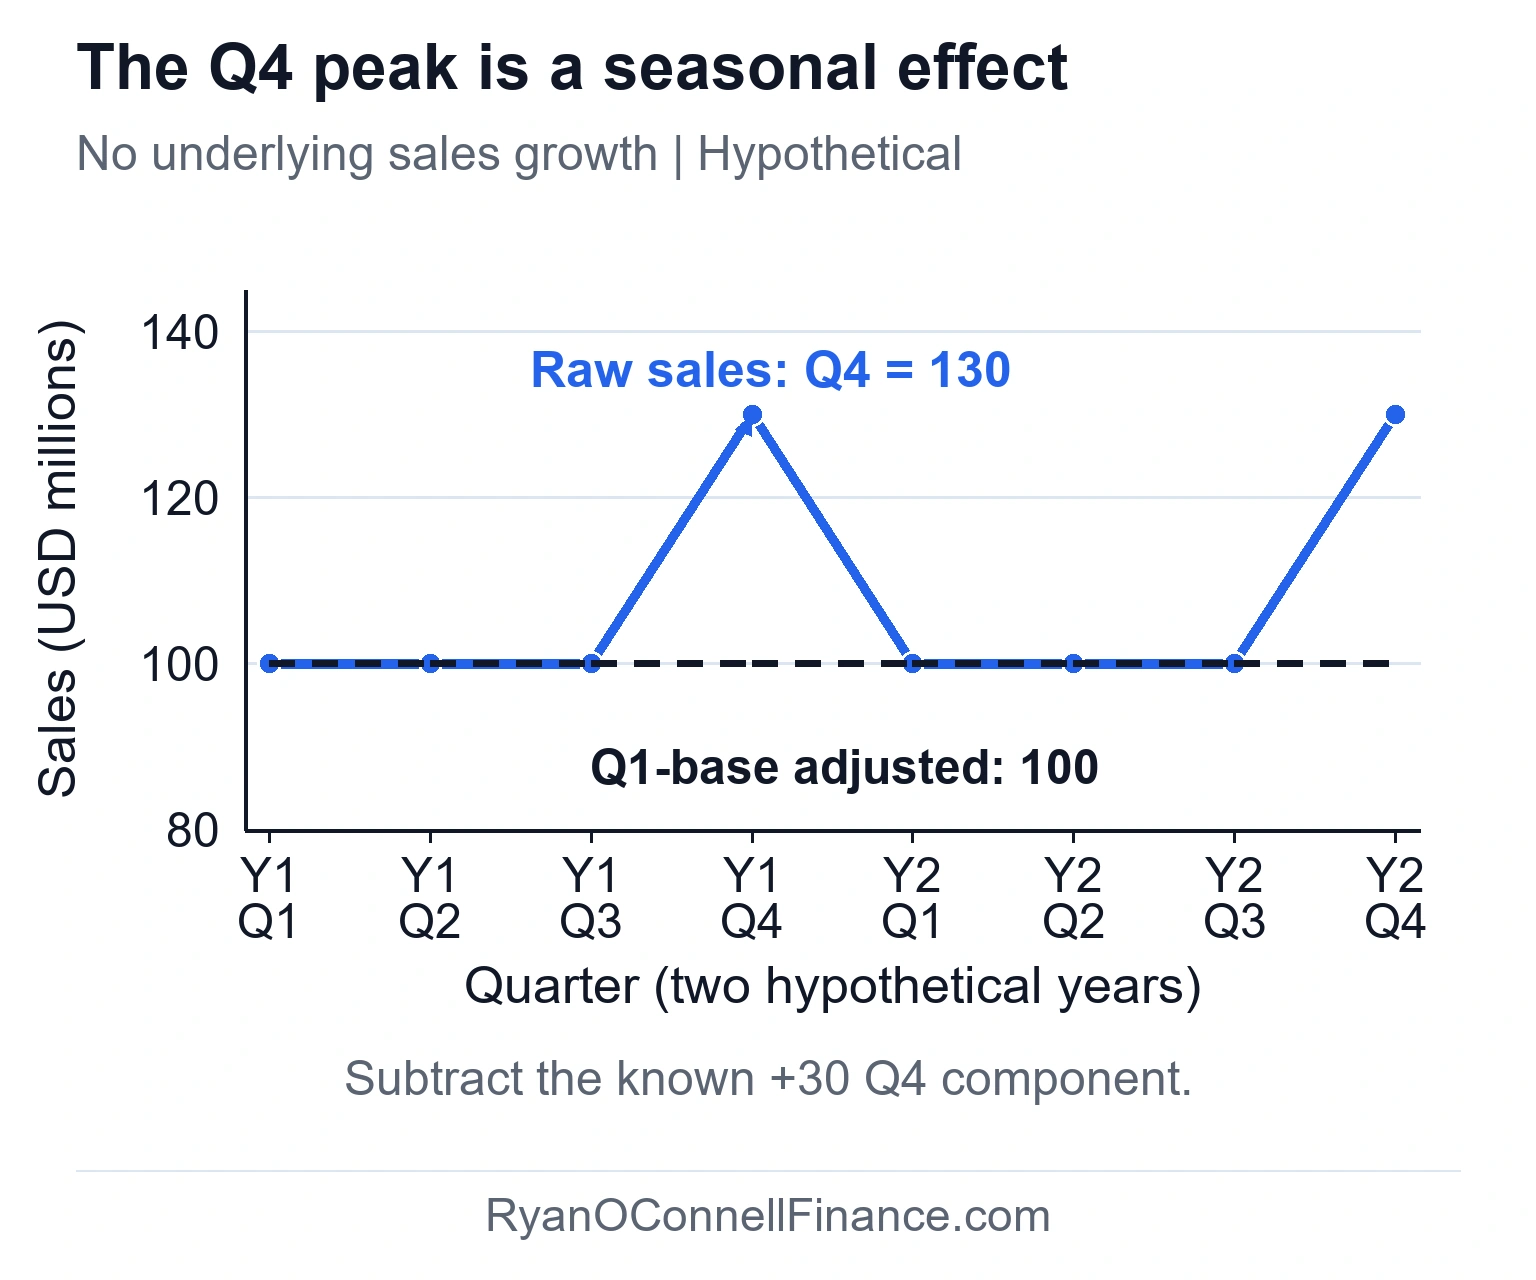
Raw sales reach $130 million in both Q4 periods, while the adjusted series stays at $100 million throughout. In this construction, the recurring peak is entirely seasonal; treating it as underlying growth would misread the pattern.
In finance, the January effect — the historical tendency for small-cap stocks to outperform in January — is a well-known seasonal anomaly that researchers control for using monthly dummy variables. Quarterly earnings announcement patterns create another form of seasonality in trading volume and return volatility.
Seasonal dummy variables are strictly exogenous by construction — the calendar does not respond to economic shocks. This makes them ideal control variables in time series regressions because they satisfy even the strongest exogeneity assumptions without any concern about feedback effects.
Many government-published series (such as quarterly GDP and monthly employment figures) are already seasonally adjusted before release. When working with pre-adjusted data, additional seasonal dummies are unnecessary and may introduce noise.
Stationarity and Weak Dependence
Two properties — stationarity and weak dependence — are essential for valid time series regression. Together, they replace the random sampling assumption used in cross-sectional econometrics.
Stationarity
Strict stationarity requires that the joint probability distribution of any collection of observations (yt1, yt2, …, ytm) is identical when shifted forward by any number of periods h. This is a strong condition rarely verified in practice.
A time series {yt} is weakly stationary if three conditions hold: (1) the mean E(yt) is constant across all time periods, (2) the variance Var(yt) is constant across all time periods, and (3) the autocovariance Cov(yt, yt+h) depends only on the lag h, not on the time period t. Weak stationarity is the practical standard used in most econometric applications.
S&P 500 returns are approximately stationary — they fluctuate around a roughly constant mean with relatively stable variance. The S&P 500 price level, however, is non-stationary because it trends upward over time (the mean changes) and its variance grows. This distinction explains why financial econometrics almost always models returns rather than prices.
Non-stationarity arises from both deterministic and stochastic trends. A series with a linear time trend is non-stationary (the mean changes with t) but can be made stationary by including the trend in the regression. A random walk is non-stationary and requires differencing.
Weak Dependence
Weak dependence means that observations far apart in time are nearly uncorrelated — formally, Corr(yt, yt+h) approaches zero as the lag h grows large. This property ensures that the past does not exert permanent influence on the future.
A stable AR(1) process with |ρ| < 1 is weakly dependent: Corr(yt, yt+h) = ρh, which decays exponentially toward zero. A random walk, by contrast, violates weak dependence because its correlation structure decays too slowly — Corr(yt, yt+h) ≈ √[t/(t+h)], which depends on the starting point t and does not vanish quickly.
For a hypothetical comparison, take two stationary quarterly AR(1) processes, each with mean zero and variance one. An AR(1) uses the previous quarter’s value plus a new independent, mean-zero shock; ρ is the fraction of the previous value carried forward. Set ρ to 0.5 in one process and 0.9 in the other, adjusting the shock variances to keep both series’ variances equal to one. Both start in their stationary distributions. The lag h counts quarters between observations; the curves give the theoretical autocorrelation ρh, rather than correlations estimated from a sample.
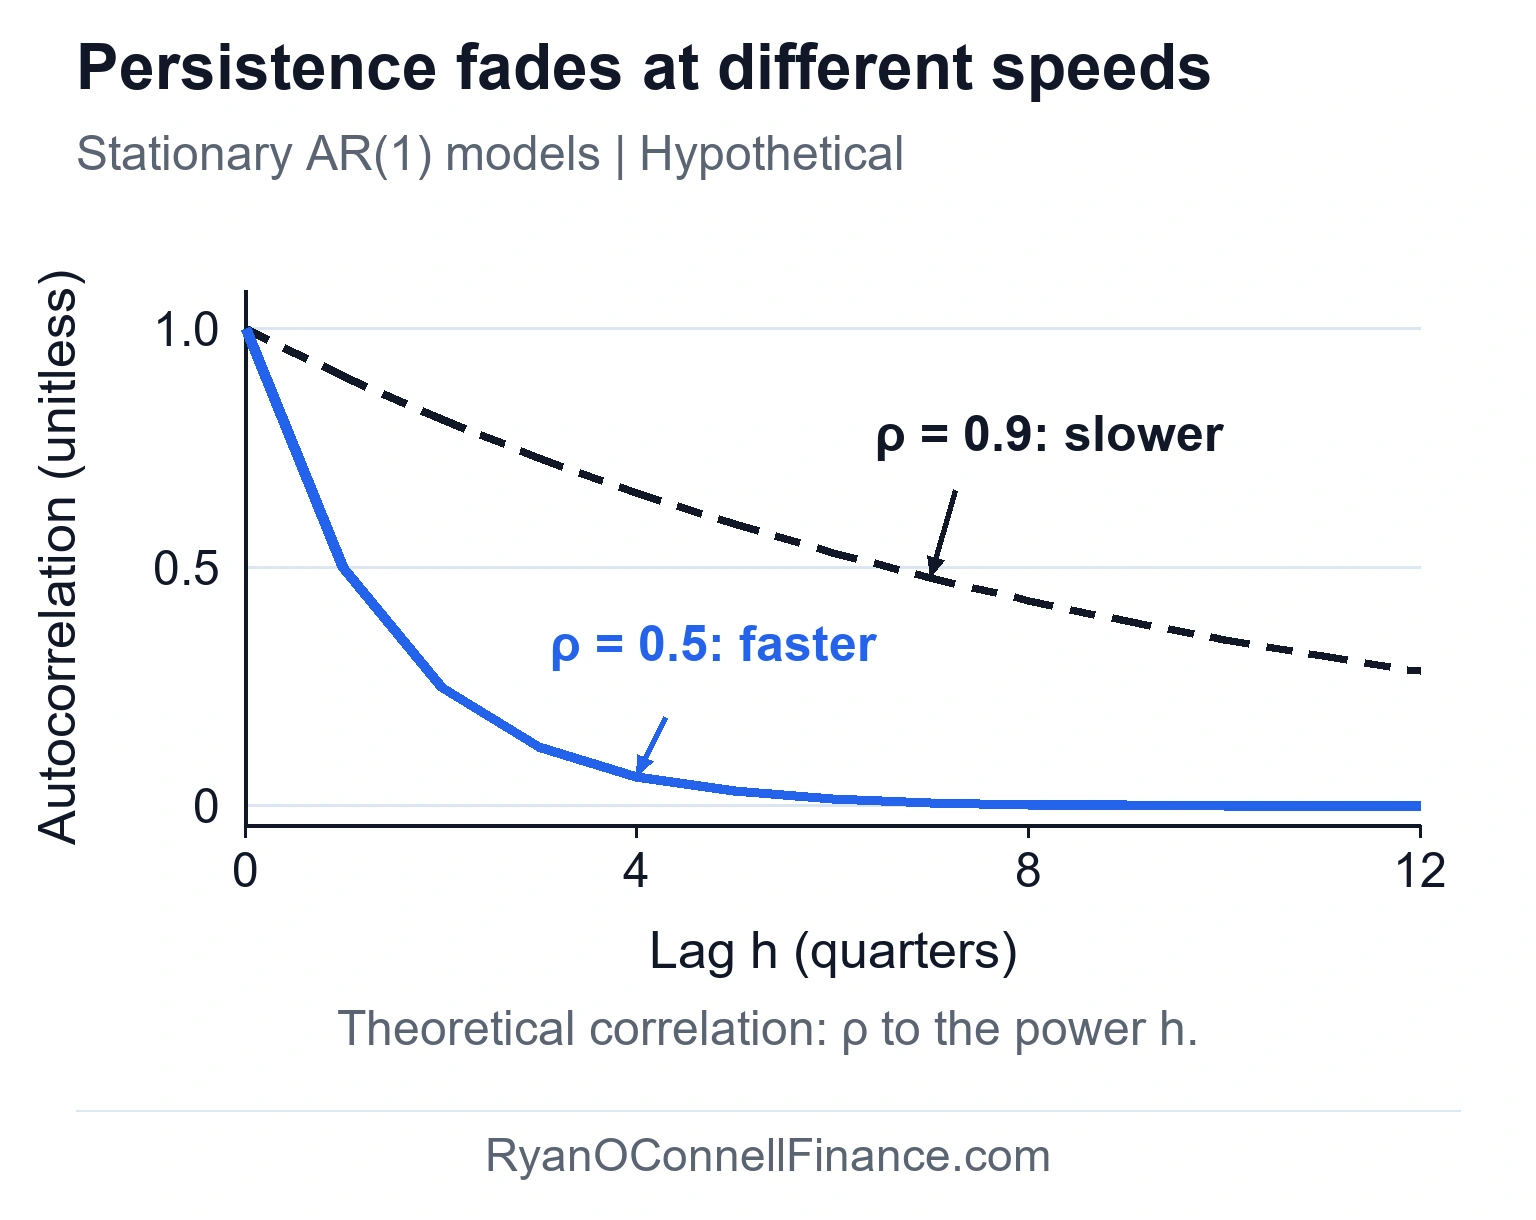
At a four-quarter lag, the correlation is about 0.06 when ρ = 0.5 and 0.66 when ρ = 0.9. Both processes are stationary and weakly dependent, yet the second retains much more information from a year earlier; stationarity does not imply independence.
Stationarity and weak dependence together ensure that the Law of Large Numbers (sample averages converge to population means) and the Central Limit Theorem (sample averages are approximately normally distributed) apply to time series data — the same tools that random sampling provides for cross-sectional data.
OLS Assumptions for Time Series
The Gauss-Markov assumptions for time series regression closely parallel the cross-sectional assumptions but differ in crucial ways. The following table highlights the key modifications:
| Assumption | Cross-Sectional (MLR) | Time Series (TS) |
|---|---|---|
| Linearity | MLR.1: Linear in parameters | TS.1: Same |
| Sampling / Dependence | MLR.2: Random sampling | TS.1′: Stationarity + weak dependence |
| Collinearity | MLR.3: No perfect multicollinearity | TS.2: Same |
| Exogeneity | MLR.4: E(ui | xi) = 0 | TS.3: E(ut | X) = 0 (strict exogeneity) |
| Homoskedasticity | MLR.5: Var(ui | xi) = σ² | TS.4: Var(ut | X) = σ² |
| No Serial Correlation | Not needed (random sampling) | TS.5: Cov(ut, us | X) = 0 for t ≠ s |
Cross-sectional regression relies on random sampling to ensure independence across observations. Time series regression cannot invoke random sampling — observations are inherently dependent. Instead, stationarity and weak dependence serve the same purpose, enabling the Law of Large Numbers and Central Limit Theorem to apply for large-sample inference.
Strict exogeneity (TS.3) requires that the error at time t is uncorrelated with explanatory variables in all time periods — past, present, and future. This is stronger than the cross-sectional assumption and is violated when explanatory variables respond to past outcomes (feedback). A weaker alternative, contemporaneous exogeneity (TS.3′), only requires E(ut | xt) = 0 — sufficient for consistency but not finite-sample unbiasedness.
Strict exogeneity fails when explanatory variables respond to past values of the dependent variable. In finance, a central bank adjusts its policy rate based on past inflation — future values of the interest rate are correlated with current inflation shocks. In this case, contemporaneous exogeneity may still hold, allowing consistent (though not unbiased) OLS estimation in large samples.
The no serial correlation assumption (TS.5) is unique to time series. It requires that regression errors are uncorrelated across time periods. When this assumption fails — which is common in static models of trending or cyclical data — standard errors are biased and hypothesis tests are unreliable. For a full treatment of diagnosing and correcting serial correlation, see our guide on Serial Correlation in Time Series.
Time Series Example: The Phillips Curve
The relationship between inflation and unemployment — the Phillips curve — provides a classic illustration of why accounting for trends matters in time series regression.
Step 1 — Static Model Without Time Trend (Flawed):
Regressing the inflation rate on the unemployment rate alone:
inf̂t = 1.05 + 0.502 × unemt n = 56, R² = 0.065
The positive coefficient (0.502) suggests higher unemployment is associated with higher inflation — the opposite of the expected tradeoff. This misleading result arises because both inflation and unemployment exhibit trending behavior over portions of this sample period. Without controlling for the shared time trend, the regression captures the spurious positive correlation between two trending series rather than the true contemporaneous relationship.
Step 2 — Adding a Linear Time Trend (Correct):
Including a time trend variable to control for the common trending behavior:
inf̂t = β̂0 + β̂1 × unemt + β̂2 × t
After including the time trend, the coefficient on unemployment (β̂1) turns negative — consistent with the expected inverse relationship between inflation and unemployment. The time trend absorbs the upward drift that both series share, allowing the regression to isolate whether above-trend unemployment is associated with below-trend inflation.
Lesson: Including a time trend is equivalent to detrending all variables first and regressing the detrended residuals. The static model without a trend suffered from a spurious positive coefficient because both series were trending. This is a textbook demonstration of why controlling for trends is essential in time series regression.
A separate hypothetical construction illustrates the mechanism without reproducing the U.S. estimates above. Take 12 annual observations, t = 1 through 12, with unemployment xt = 4 + 0.15t + et and inflation yt = 1 + 0.25t − 0.70et, both measured in percent. The constructed fluctuation e has no fitted linear time trend or nonzero sample mean, and there is no additional noise. Both baseline rates rise over time, while the same fluctuation moves the two rates in opposite directions. Compare the raw observations with deviations after removing each variable’s separately fitted intercept and linear time trend; those deviations are measured in percentage points (pp).
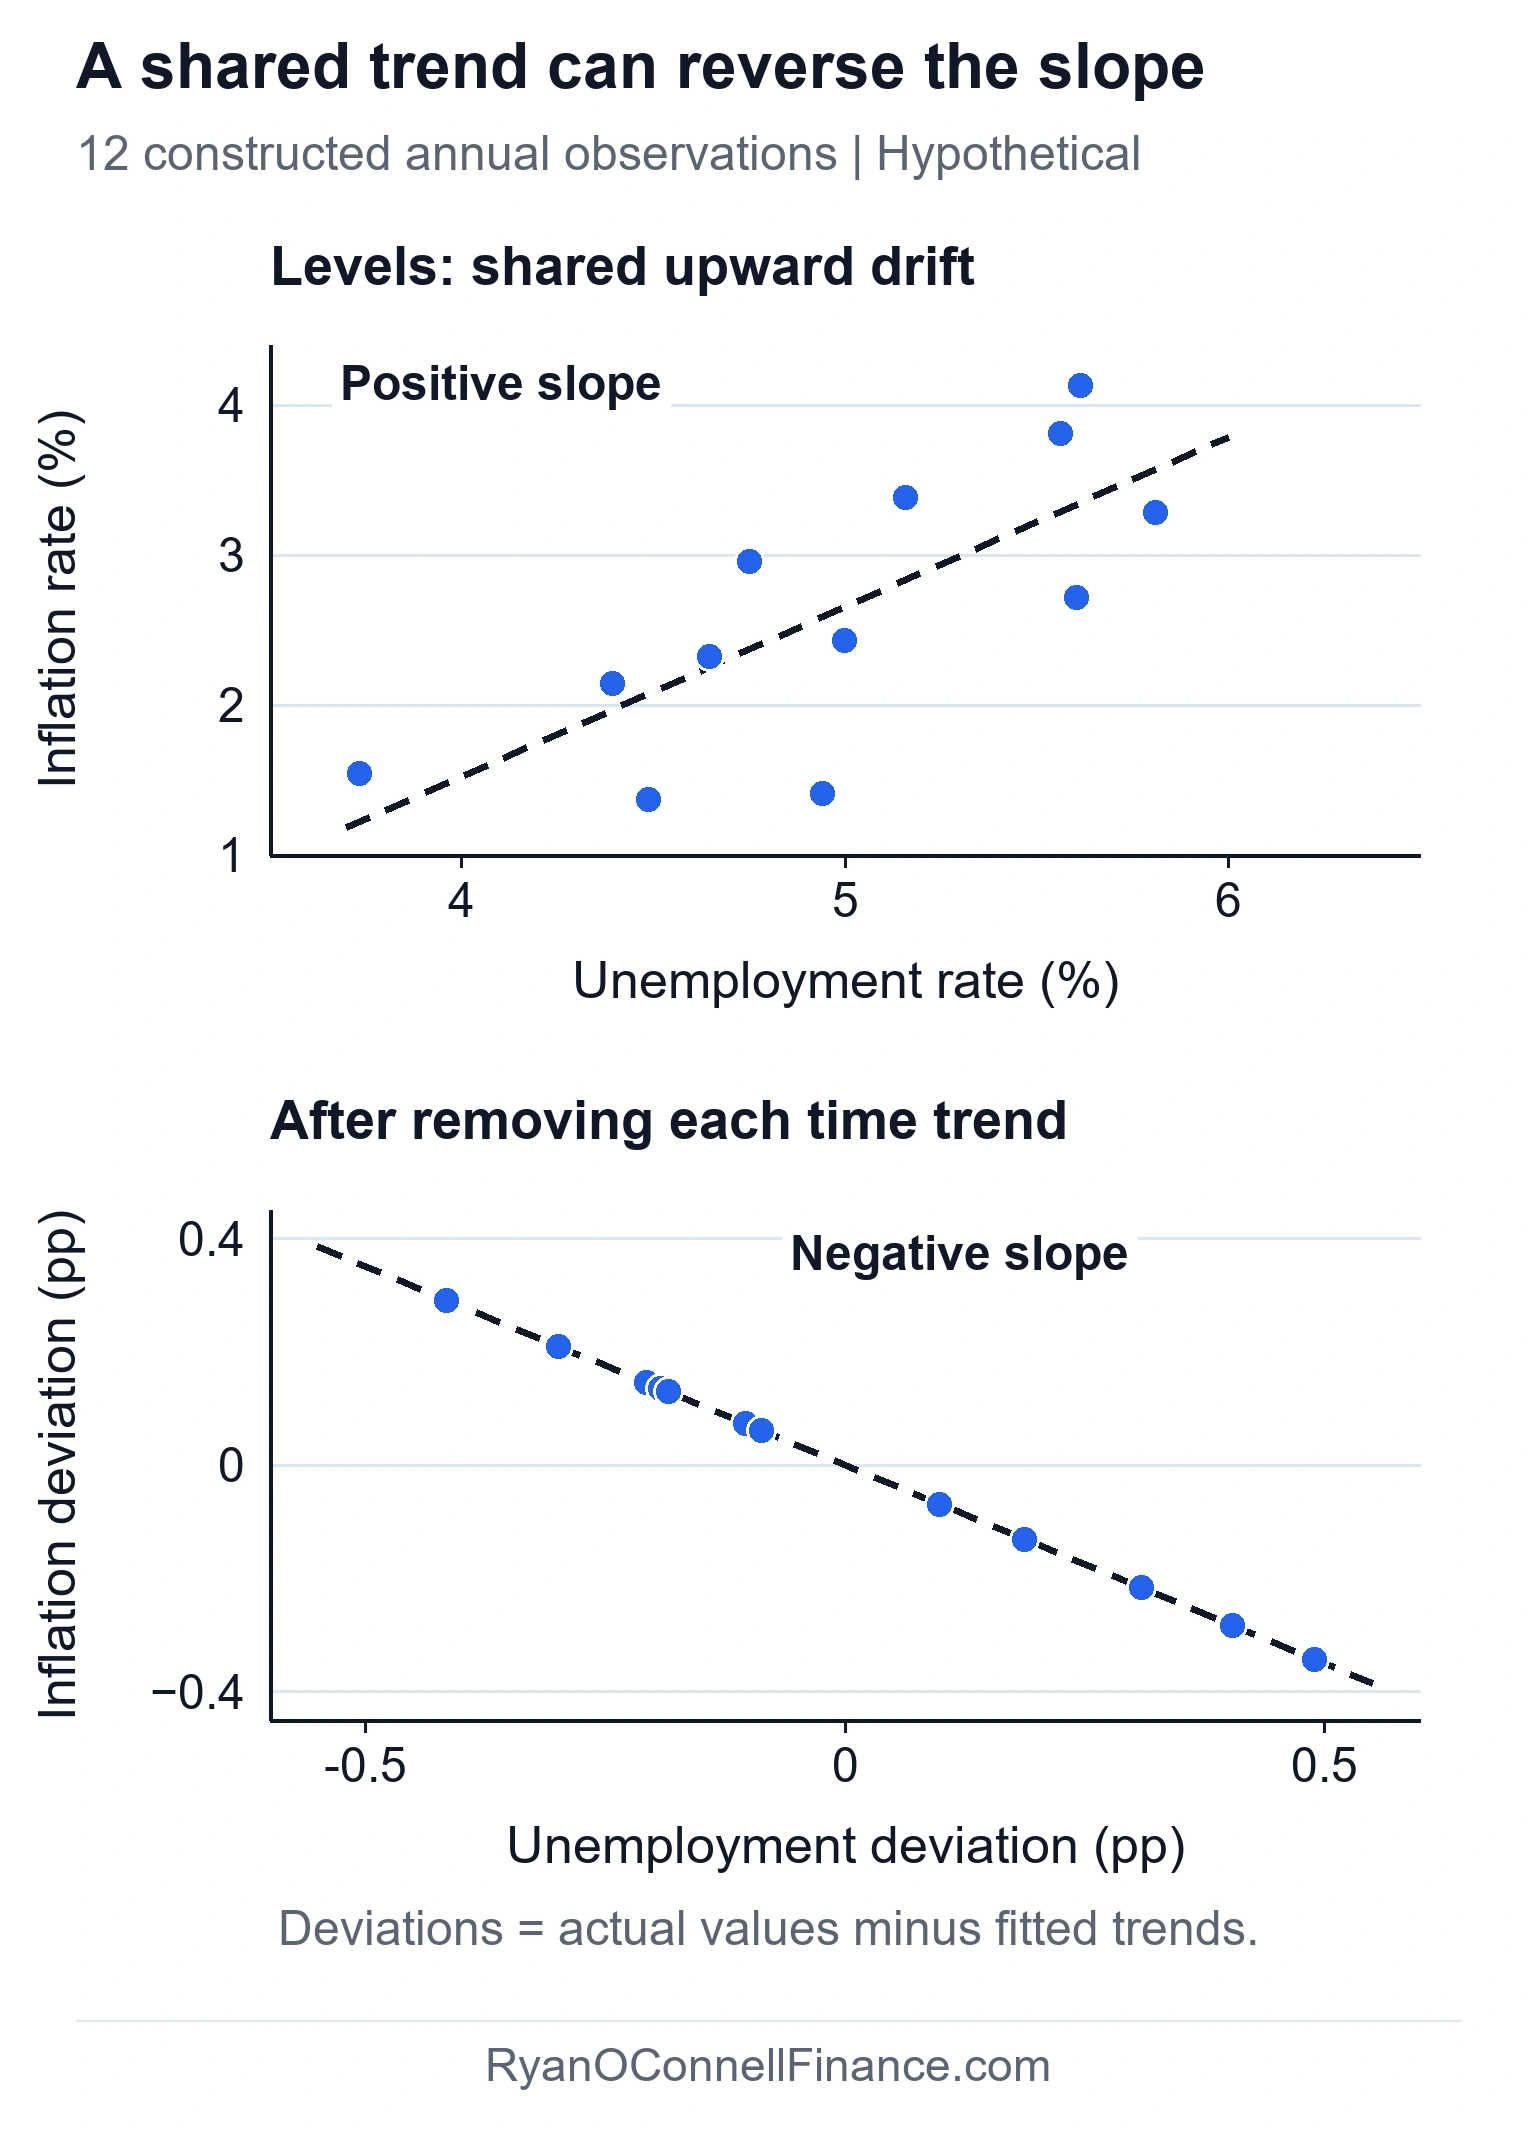
The raw association is positive because the shared upward drift dominates the fluctuations. Once each linear trend is removed, the remaining relationship has a slope of −0.70: a 1 percentage point larger unemployment deviation corresponds to a 0.70 percentage point smaller inflation deviation in this construction. That coefficient also equals the unemployment coefficient in a regression including the time trend. This illustrates a change in association; detrending alone does not establish a causal Phillips curve.
Including a time trend variable (t = 1, 2, 3, …) in a regression is equivalent to detrending all variables first and then running the regression on the detrended values. This is the simplest way to control for deterministic trends. For series with stochastic trends (random walks), first-differencing (Δyt = yt − yt−1) is typically needed instead.
Static vs. Distributed Lag Models
Choosing between a static model and a finite distributed lag model depends on the nature of the relationship being studied. The following comparison highlights their key differences:
Static Model
- Contemporaneous relationship only: yt = β0 + β1zt + ut
- Effect of z on y is immediate and complete
- Simpler to estimate and interpret
- β1 captures the full effect of a one-unit change in z
- Best when: effects are instantaneous (same-day market reactions, contemporaneous tradeoffs)
Finite Distributed Lag Model
- Allows z to affect y over q periods: includes zt, zt−1, …, zt−q
- Effect unfolds gradually over time
- Impact propensity (δ0): immediate one-period effect
- Long-run propensity (Σδ): total cumulative effect
- Best when: effects are delayed (policy transmission, investment lags, credit market adjustments)
In practice, the choice depends on domain knowledge. Monetary policy effects typically require distributed lags because interest rate changes take quarters to transmit through credit markets to real economic activity. By contrast, exchange rate changes may have immediate effects on import prices, making a static model reasonable.
Common Mistakes in Time Series Regression
Time series regression introduces pitfalls that do not arise in cross-sectional settings. Avoiding these mistakes is essential for valid inference:
1. Ignoring Trends and Running Spurious Regressions — Two unrelated trending series can produce a high R² and significant t-statistics purely because both variables are growing over time. Always check whether your dependent and explanatory variables exhibit trends, and include a time trend variable or detrend the data before estimation.
2. Applying Cross-Sectional Assumptions to Time Series — The random sampling assumption that justifies standard cross-sectional inference does not hold for time series data. Strict exogeneity is a stronger requirement in time series because it rules out feedback from past outcomes to future explanatory variables. Using cross-sectional intuition without adapting to the time series context produces invalid standard errors and test statistics.
3. Confusing Temporal Correlation with Contemporaneous Causation — The fact that yt is correlated with yt−1 (serial correlation in the dependent variable) does not mean that a contemporaneous regressor xt causes yt. Persistence in the dependent variable is a feature of time series data that must be modeled, not evidence of a causal effect.
4. Ignoring Seasonality in Sub-Annual Data — Failing to include seasonal dummies when monthly or quarterly data exhibit seasonal patterns can bias coefficient estimates and produce misleading significance tests. Always test for seasonality with a joint F-test on the seasonal dummy variables before concluding that seasonality is absent.
5. Assuming Stationarity Without Checking — Running OLS on non-stationary series (such as random walks) without detrending or differencing produces unreliable estimates. The variance of a random walk grows over time, violating the conditions needed for the Law of Large Numbers and Central Limit Theorem to apply. Examine time series plots and first-order autocorrelations before specifying a model.
Limitations of Time Series Regression
Time series regression is a powerful framework, but it has important limitations that affect real-world applications:
Time series regression requires stationarity and weak dependence for valid large-sample inference. Highly persistent series — such as interest rates, exchange rates, and asset prices in levels — may violate these conditions and require specialized methods like differencing, cointegration analysis, or error correction models.
Strict Exogeneity Is Often Unrealistic — In economics and finance, explanatory variables frequently respond to past outcomes. Central banks adjust policy rates based on past inflation, firms adjust investment based on past profitability, and regulators adjust rules based on past crises. This feedback violates strict exogeneity, limiting OLS to consistency (not unbiasedness) under the weaker contemporaneous exogeneity assumption.
Small Sample Sizes — Annual economic data may span only 30 to 70 observations, sharply limiting the power of hypothesis tests and the reliability of asymptotic approximations. Even quarterly data rarely exceeds a few hundred observations for most macroeconomic applications.
Structural Breaks — If the underlying relationship changes during the sample period — for example, before and after the 2008 financial crisis — a single regression across the full period is misspecified. The estimated coefficients represent an average of two different regimes rather than the true relationship in either one.
Nonlinear Dynamics — Standard time series regression assumes linear relationships. It cannot capture phenomena like volatility clustering (periods of high volatility tend to follow other periods of high volatility) or regime switching. These features require extensions such as GARCH models or Markov-switching specifications.
Time series regression provides the foundational framework for modeling dynamic relationships in finance and economics. Valid inference requires careful attention to trends, seasonality, stationarity, and the adapted OLS assumptions. When these conditions are met, OLS remains a powerful and interpretable tool for estimating causal and predictive relationships over time.
Frequently Asked Questions
Disclaimer
This article is for educational and informational purposes only and does not constitute investment advice. Regression results cited are illustrative and based on textbook datasets. Actual econometric analysis requires careful attention to data sources, sample periods, and model specification. Always consult the primary academic literature and a qualified professional before applying these methods to investment decisions.
Keep reading
Next in this series
Part 10 of 17 in Econometrics: From Regression to Causal Inference
Serial Correlation: Durbin-Watson Test, HAC Standard Errors & FGLSMore in Econometrics
-
What Is Econometrics? Data Types, Causality & the Empirical Process
Econometrics applies statistical methods to economic and financial data to estimate relationships, test theories, and evaluate decisions.
-
Simple Linear Regression: The OLS Method Explained
Learn simple linear regression and the OLS method. Understand the population model, slope and intercept interpretation, R-squared, and key assumptions…
-
Causal Inference in Econometrics: RDD, Propensity Scores & Treatment Effects
A unified framework for causal inference in econometrics. Covers the potential outcomes framework, selection bias, ATE vs ATT vs LATE, randomized controlled…


